Picture this. One of your availability zones is down for maintenance when an entire region goes offline. Can your payments database still commit writes?
That’s where replication factor 9 (RF 9) comes in. Starting with YugabyteDB Anywhere (YBA) v2026.1.3.0, you can create a primary cluster with RF 9 or raise an existing primary cluster to RF 9.
When would you use RF 9?
Let’s give that payments database three regions with three zones each. With one voting replica per tablet in each zone, losing an entire region takes out three replicas. Losing another zone elsewhere takes out one more. That leaves five of nine, which is just enough for a Raft majority.
Now picture the same outage on an RF 7 cluster laid out 3 / 2 / 2. Losing the three-zone region still leaves four replicas, enough for a majority. But once another zone goes offline, that drops to three. The middle row shows exactly where the two layouts behave differently.
| Failure scenario | RF 7 across 3 regions (3 / 2 / 2) | RF 9 across 3 regions (3 / 3 / 3) |
|---|---|---|
| A three-zone region goes offline | 4 of 7 remain. Quorum holds. | 6 of 9 remain. Quorum holds. |
| That region plus one zone elsewhere go offline | 3 of 7 remain. Quorum is lost. | 5 of 9 remain. Quorum holds. |
| Any two regions go offline | At most 3 of 7 remain. Quorum is lost. | 3 of 9 remain. Quorum is lost. |
Create an RF 9 primary cluster
Let’s build the 3 / 3 / 3 layout from the example. The new YBA UI lets you choose RF 9 in Expert mode, and the Classic UI exposes it in the cloud configuration. Both start with the same global setting. Plan your universe
1. Enable RF 9 in YBA
RF 9 is disabled by default, so start in the admin settings. Sign in as a Super Admin, head to Admin → Advanced → Global Configuration, and search for Enable primary replication factor 9. Open the setting’s Actions menu, choose Edit Configuration, set it to True, and save. Runtime configuration · RF 9 behavior
yb.universe.enable_primary_rf_9. If a Super Admin later turns it off, universes already configured with RF 9 keep their replication factor.2. Choose RF 9 and select your nine zones
Now open Create Universe and pick the provider you prepared. In the new UI, head to Placement → Regular Cluster → Expert. Select your three regions, set Replication Factor to 9, and add three zones from each region. Give each zone at least one node or pod, then finish the wizard.
If you’re following along in the Classic UI, look under Cloud Configuration. Select the regions, set Replication Factor to 9, and use Add Zone to build the same nine-zone layout.
3. Verify the placement
Once YBA finishes creating the universe, take a look at what it actually deployed. The primary cluster should show RF 9 and span the nine zones you picked. Open Nodes (or Pods on Kubernetes) and look for nine running YB-Masters, one in each zone. An Under-replicated master alert is a reason to stop here and investigate.
PLAT-23267). On-premises deployments with dedicated masters have a separate issue when a zone has more free master instances than TServer nodes (PLAT-23296). Verify the running master count even after the task succeeds. YBA release notes and known issuesSo far, we’ve looked at the cluster in YBA. Now let’s follow the payments data. Once replica placement has settled, we should be able to pick any tablet in our example and find three replicas in each region, one per zone. In YSQL, yb_tablet_metadata gives us the replica addresses and yb_servers() tells us where those servers live.
To try it on your cluster, connect to the database that contains your test table and swap public.payments for a schema-qualified table that inherits the primary cluster’s placement.
					console.log( 'Code is Poetry' );SELECT
    t.tablet_id,
    count(DISTINCT r.endpoint) FILTER (
        WHERE s.node_type = 'primary'
    ) AS primary_replicas,
    array_agg(DISTINCT concat_ws('.', s.cloud, s.region, s.zone)) FILTER (
        WHERE s.node_type = 'primary'
    ) AS primary_zones,
    count(DISTINCT r.endpoint) FILTER (
        WHERE s.host IS NULL
    ) AS unmatched_endpoints
FROM yb_tablet_metadata AS t
LEFT JOIN LATERAL unnest(t.replicas) AS r(endpoint) ON true
LEFT JOIN yb_servers() AS s
    ON r.endpoint IN (
        s.host || ':' || s.port,
        s.public_ip || ':' || s.port
    )
WHERE t.db_name = current_database()
  AND t.oid = 'public.payments'::regclass
GROUP BY t.tablet_id
ORDER BY t.tablet_id;
Read the result one tablet at a time. For each row, we’re looking for 9 in primary_replicas and all nine intended zones in primary_zones. That count covers primary-cluster nodes. If unmatched_endpoints is above zero, check those addresses first. The query couldn’t assign those addresses to a zone.
If one tablet catches your eye, use its tablet_id with yb-admin list_tablet_servers <tablet-id> to inspect its peers. The SQL result tells you where replicas live. Check Raft voting status separately. yb-admin reference
yb_tablet_metadata and map a row to its tablet and leader. Exploring Tablet Placement with yb_tablet_metadataRaise an existing primary cluster to RF 9
What if your payments database is already running on RF 7? You can raise the RF on an existing VM-based universe or a Kubernetes universe managed directly by YBA. If you use the YugabyteDB Kubernetes Operator, the replication factor is fixed after creation. Placement change limits
In the new UI, open Settings → Placement. On the Primary Cluster card, choose Edit → Edit Regions, switch to Expert if needed, and set RF to 9. Continue to node placement and check that all nine zones are represented before you apply the change.
In the Classic UI, you’ll find the same settings under Actions → Edit Universe → Cloud Configuration. Update Replication Factor, Total Nodes, and Availability Zones, then save. Modify a universe
Final thoughts
For the payments team, I’d make the decision by asking whether that second outage has to fit inside the availability target. If the database needs to keep committing writes through a regional outage while another zone is already down, the 3 × 3 layout gives the team the five votes it needs.
Then I’d ask what those extra two copies per tablet cost. They take more storage and replication traffic, and writes need a five-voter majority. The way to find out whether the trade-off works for your application is to run the workload through the failure you’re planning for.
Have Fun!
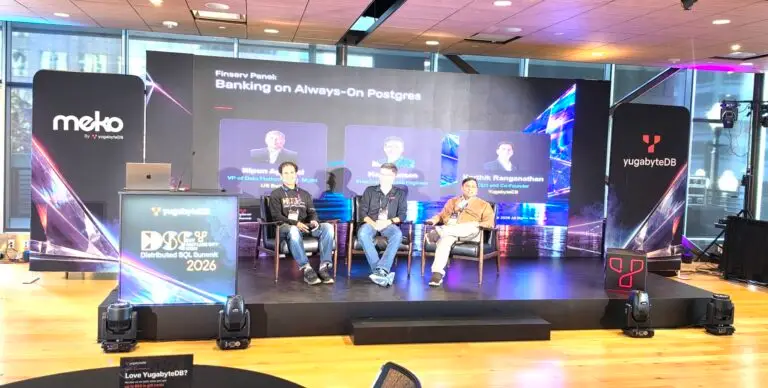
One of my favorite conversations at the Distributed SQL Summit in Salt Lake City! “Banking on Always-On Postgres” brought together Marc Hansen (Principal Database Engineer, Fiserv) and Nipun Agarwal (VP of Data Platform Product Management, U.S. Bank) for a fireside chat with Karthik Ranganathan (Co-Founder and Co-CEO, YugabyteDB).
I especially enjoyed hearing why their teams moved to distributed SQL, how they managed migration risk, what changed for their operations teams, and what they’d do differently. My biggest takeaway? In financial services, resilience and scalability are king.