Build a Distributed RAG Pipeline from YSQL with pg_dist_rag

In Part 1 of this series, What Is RAG? From PostgreSQL pgrag to Distributed RAG with YugabyteDB pg_dist_rag, we looked at Retrieval-Augmented Generation (RAG), why vector search is only one piece of the problem, and how YugabyteDB’s pg_dist_rag extension takes a distributed approach to document preprocessing.

Now it is time to build one.

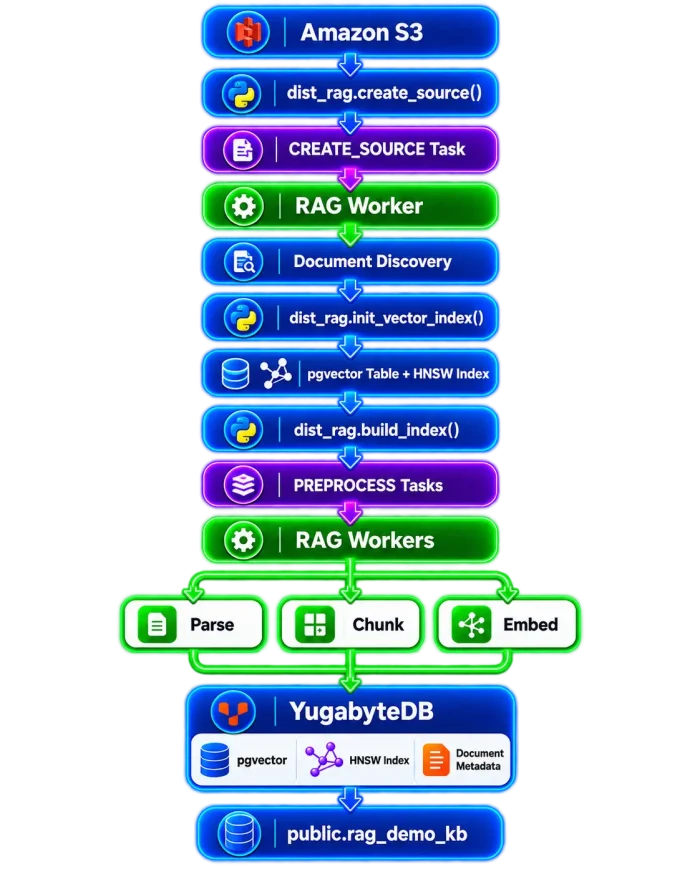
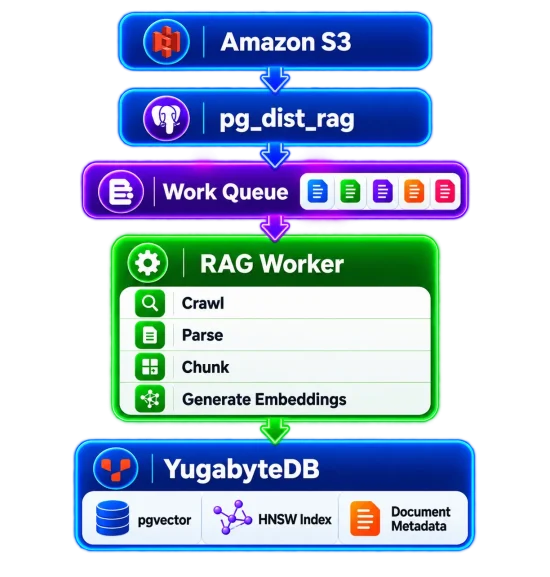
In this tip, we will take a small collection of Markdown documents stored in Amazon S3 and turn them into searchable vector embeddings using:

RAG-Pipeline2

The interesting part is how little application-specific pipeline code we need to write.

Much of the pipeline is defined and managed from YSQL using functions provided by pg_dist_rag. The extension registers sources, manages pipeline state, queues work, tracks documents, creates the pgvector-backed table, and provides views for monitoring the pipeline.

External Python workers then claim work from YugabyteDB and perform the compute-intensive crawling, parsing, chunking, and embedding operations.

What Does “from YSQL” Mean?

YSQL acts as the control plane for the RAG pipeline. The compute-intensive work does not run inside the database backend. External RAG workers crawl, parse, chunk, and embed documents, while YugabyteDB manages the work queue, pipeline state, metadata, and resulting vectors.
What We Are Going to Build

For this demo, we will create a tiny fictional operations knowledge base consisting of three Markdown documents:

				
					rag-demo/
|
+-- availability.md
+-- backups.md
+-- scaling.md


The content itself is intentionally simple. The goal of this tip is not to build an impressive AI application yet.

The goal is to watch the complete distributed preprocessing pipeline work.

By the end of the demo, we will have:

S3 Documents
|
v
Registered Source
|
v
Discovered Documents
|
v
PREPROCESS Tasks
|
v
RAG Worker
|
v
Chunks + Embeddings
|
v
public.rag_demo_kb
|
v
HNSW Vector Index

And in our actual test, those three documents ultimately produced:

  • ● 3 documents
  • ● 12 chunks
  • ● 12 embeddings
  • ● 12 Rows in YugabyteDB

Prerequisites

Requirement Purpose
YugabyteDB v2026.1.1+ Database containing the pg_dist_rag extension.
pgvector Stores embeddings and provides vector similarity search.
Python 3.11 Runs the external RAG worker.
OpenAI API Key Generates document embeddings.
Amazon S3 Stores the source documents for this demo.
Tech Preview

pg_dist_rag is currently intended for evaluation and experimentation. Review the current YugabyteDB documentation and support status before considering it for production workloads.

OpenAI API Billing Is Separate

Having a ChatGPT subscription does not provide OpenAI API quota. ChatGPT and the API Platform use separate billing systems. Make sure the API project associated with OPENAI_API_KEY has available billing or prepaid credits before starting the embedding pipeline.

Step 1: Create Some Demo Documents

We will use Markdown documents so that PDF/OCR dependencies are not required for this demo.

Create a directory:

				
					mkdir -p rag-demo
cd rag-demo


Create availability.md:

				
					cat > availability.md <<'EOF'
# Availability

The Acme Payments production service is deployed across three availability zones.

Database maintenance should be performed gradually so that the application remains available while individual infrastructure components are serviced.

Production changes must be validated before proceeding to the next stage.
EOF


Create backups.md:

				
					cat > backups.md <<'EOF'
# Backups

The Acme Payments platform creates scheduled backups of production data.

Backup jobs are monitored for successful completion and recovery procedures are tested regularly.

A backup should not be considered useful until the organization has verified that it can be restored.
EOF


Create scaling.md:

				
					cat > scaling.md <<'EOF'
# Scaling

The Acme Payments operations team monitors database utilization and application latency.

When sustained workload growth requires additional capacity, infrastructure can be expanded rather than waiting for resource exhaustion.

Scaling decisions should consider CPU utilization, storage growth, connection demand, and application latency.
EOF


Now upload them to an S3 bucket that the RAG worker can access:

				
					export RAG_BUCKET=<your-s3-bucket>

aws s3 sync ./ s3://${RAG_BUCKET}/rag-demo/


Verify:

				
					aws s3 ls s3://${RAG_BUCKET}/rag-demo/


You should see the three Markdown files.

Replace the Placeholder Before Running the SQL

Throughout this tip, values such as <your-s3-bucket> are placeholders. Replace them with real values before executing the commands. Otherwise, you can accidentally register a literal source URI such as s3://<your-s3-bucket>/rag-demo/.

Step 2: Enable the Extensions

Connect to YugabyteDB using ysqlsh.

Install vector first and then pg_dist_rag:

				
					CREATE EXTENSION IF NOT EXISTS vector;
CREATE EXTENSION IF NOT EXISTS pg_dist_rag;


The second command creates the dist_rag schema with the objects needed to manage sources, indexes, documents, pipelines, and the work queue.

Verify the extensions:

				
					SELECT
    extname,
    extversion
FROM pg_extension
WHERE extname IN ('vector', 'pg_dist_rag')
ORDER BY extname;


Our test environment returned:

				
					.  extname   |  extversion
-------------+--------------
 pg_dist_rag | 0.0.1
 vector      | 0.8.0-yb-1.0


Take a look at what pg_dist_rag created:

				
					SELECT
    table_schema,
    table_name
FROM information_schema.tables
WHERE table_schema = 'dist_rag'
ORDER BY table_name;
				
			
Among the important tables are:
  • dist_rag.sources
  • dist_rag.vector_indexes
  • dist_rag.vector_index_source_mappings
  • dist_rag.documents
  • dist_rag.pipeline_details
  • dist_rag.work_queue

Step 3: Configure the RAG Worker… But Do Not Start It Yet

The RAG worker is included with the YugabyteDB installation.

On the machine that will run the worker:

				
					cd <yugabytedb-install-dir>/python/ai/rag_agent


Create a Python 3.11 virtual environment:

				
					uv venv --python=3.11
source .venv/bin/activate
uv pip install -r requirements.txt


Configure the worker:

				
					export YUGABYTEDB_CONNECTION_STRING="postgresql://yugabyte:<password>@<node-address>:5433/yugabyte"

export OPENAI_API_KEY="<your-openai-api-key>"

export AWS_REGION="us-east-1"
export AWS_ACCESS_KEY_ID="<key-id>"
export AWS_SECRET_ACCESS_KEY="<secret-key>"


Public S3 objects do not require the AWS access-key variables.

The default worker type is TEXT, which processes non-PDF documents. A PDF-specific worker can be started by additionally setting:

				
					export WORKER_DOCUMENT_TYPE=PDF


Do not start the worker yet.

We deliberately leave it stopped so we can see what pg_dist_rag places in the work queue.

Why Leave the Worker Stopped?

The demo documents are tiny, so workers can claim and complete tasks almost immediately. Leaving the worker stopped temporarily makes it much easier to see exactly what pg_dist_rag places in dist_rag.work_queue.

Step 4: Register the S3 Source

Now return to ysqlsh.

Register the document location:

				
					SELECT dist_rag.create_source(
    r_source_uri := 's3://<your-s3-bucket>/rag-demo/',
    r_metadata := '{
        "demo": "rag_series",
        "content_type": "operations"
    }'::jsonb
) AS source_id \gset


Display the returned UUID:

				
					\echo :source_id


Because the worker is not running, the source remains queued.

Inspect the source:

				
					SELECT
    id,
    source_uri,
    status,
    created_at,
    completed_at
FROM dist_rag.sources
ORDER BY created_at;


Our run showed:

				
					.                 id                  |          source_uri          | status | completed_at
--------------------------------------+------------------------------+--------+-------------
 1a0c4f8a-c73b-43dc-b83c-06174d79114c | s3://jimk-rag-demo/rag-demo/ | QUEUED |


Now inspect the work queue:

				
					SELECT
    id,
    task_type,
    task_status,
    task_details,
    current_worker,
    lease_acquired_at,
    lease_expires_at,
    created_at
FROM dist_rag.work_queue
ORDER BY created_at;


Because the worker is stopped, we can clearly see the task:

				
					.  task_type   | task_status | task_details
---------------+-------------+------------------------------------------------------------
 CREATE_SOURCE | QUEUED      | {"source_id": "...", "tenant_id": null}
				
			
This Is the First Distributed Handoff

create_source() does not crawl S3 itself. It creates a CREATE_SOURCE task in dist_rag.work_queue. An external worker claims that task and performs the source discovery.

At this point, no documents have been discovered yet:

				
					SELECT
    document_id,
    document_name,
    status
FROM dist_rag.documents
WHERE source_id = :'source_id'::uuid;


Result:

				
					(0 rows)


Step 5: Start the Worker and Discover the Documents

Now start the worker:

				
					python __main__.py


The worker claims the CREATE_SOURCE task, crawls the S3 location, and registers each document.

Check the source again:

				
					SELECT
    id,
    source_uri,
    status,
    created_at,
    completed_at
FROM dist_rag.sources;


Our run now showed:

				
					.       source_uri             | status
-------------------------------+-----------
s3://jimk-rag-demo/rag-demo/   | COMPLETED


Now inspect the discovered documents:

				
					SELECT
    document_id,
    document_name,
    document_uri,
    document_type,
    status
FROM dist_rag.documents
WHERE source_id = :'source_id'::uuid
ORDER BY document_name;


Sample output:

				
					.     document_name       | document_type | status
--------------------------+---------------+--------
 rag-demo/availability.md | text/markdown | QUEUED
 rag-demo/backups.md      | text/markdown | QUEUED
 rag-demo/scaling.md      | text/markdown | QUEUED


Now query the work queue again:

				
					SELECT *
FROM dist_rag.work_queue
ORDER BY created_at;


Output:

				
					(0 rows)
				
			
That reveals an important architectural detail.
The Work Queue Is a Live Dispatch Queue

dist_rag.work_queue is not intended to be permanent task history. Once a successfully processed task is finished, it disappears from the live queue. Persistent source, document, and pipeline state is maintained in the other dist_rag objects.

At this point:

				
					Source             COMPLETED

Documents          3 discovered

Document Status    QUEUED

Work Queue         Empty


Now stop the worker again with Ctrl-C.

We want it stopped before creating the preprocessing workload.

Step 6: Create the Vector Index

Now create the knowledge base.

For this Markdown demo, explicitly provide the embedding model, dimensions, and chunking configuration:

				
					SELECT dist_rag.init_vector_index(
    r_index_name := 'rag_demo_kb',
    r_sources := ARRAY[:'source_id']::UUID[],
    r_chunk_params := '{
        "splitter": "markdown",
        "args": "{\"chunk_size\": 1000, \"chunk_overlap\": 100}"
    }'::jsonb,
    r_ai_provider := 'OPENAI',
    r_embedding_model_params := '{
        "model": "text-embedding-3-small",
        "dimensions": 1536
    }'::jsonb
) AS index_id \gset


Display the returned index ID:

				
					\echo :index_id


Inspect the vector-index definition:

				
					SELECT
    index_name,
    schema_name,
    ai_provider,
    embedding_model_params,
    index_options
FROM dist_rag.vector_indexes
WHERE id = :'index_id'::uuid;


Our run returned:

				
					index_name  | rag_demo_kb
schema_name | public
ai_provider | OPENAI

embedding_model_params
---------------------------------------------------------
{"model": "text-embedding-3-small", "dimensions": 1536}

index_options
------------------------------------------------------------
{"m": 16, "distance_metric": "cosine", "ef_construction": 64}


Now inspect the source mapping:

				
					SELECT
    index_id,
    source_id,
    chunk_params
FROM dist_rag.vector_index_source_mappings
WHERE index_id = :'index_id'::uuid;


Output:

				
					chunk_params
-----------------------------------------------------------------------------------
{"args": "{\"chunk_size\": 1000, \"chunk_overlap\": 100}", "splitter": "markdown"}


Step 7: Examine the Generated pgvector Table

init_vector_index() creates a real YSQL table.

Run:

				
					\d public.rag_demo_kb


Our demo produced:

				
					                         Table "public.rag_demo_kb"

      Column      |     Type     | Nullable
------------------+--------------+----------
 id               | uuid         | not null
 chunk_text       | text         | not null
 embeddings       | vector(1536) | not null
 document_id      | uuid         | not null
 tenant_id        | uuid         |
 metadata_filters | jsonb        | not null

Indexes:
    "rag_demo_kb_pkey" PRIMARY KEY, lsm (id HASH)
    "idx_rag_demo_kb_embeddings" ybhnsw (embeddings vector_cosine_ops)


We can also query pg_indexes:

				
					SELECT
    indexname,
    indexdef
FROM pg_indexes
WHERE schemaname = 'public'
  AND tablename = 'rag_demo_kb';


Output:

				
					.        indexname          | indexdef
----------------------------+---------------------------------------------------------------
 rag_demo_kb_pkey           | CREATE UNIQUE INDEX ... USING lsm (id HASH)
 idx_rag_demo_kb_embeddings | CREATE INDEX ... USING ybhnsw
                              (embeddings vector_cosine_ops)
				
			
This Is a Normal YSQL Table

The resulting knowledge base is not hidden inside a separate vector service. The chunks, embeddings, document identifiers, tenant identifiers, and JSONB metadata are stored directly in a YSQL table, with a YugabyteDB HNSW index over the vector column.

Step 8: Queue the Document Preprocessing

The worker is still stopped.

Run:

				
					SELECT dist_rag.build_index(
    r_index_name := 'rag_demo_kb'
);


Our run reported:

				
					NOTICE:  Documents queued for preprocessing: 3; skipped (already PROCESSING/COMPLETED): 0
NOTICE:  Index build kicked off for index_id: ...; documents queued: 3


Now inspect the work queue:

				
					SELECT
    id,
    task_type,
    task_status,
    task_details->>'document_name' AS document_name,
    current_worker,
    lease_acquired_at,
    lease_expires_at,
    created_at
FROM dist_rag.work_queue
ORDER BY created_at;


This gives us one of the most useful outputs in the demo:

				
					.task_type  | task_status |      document_name
------------+-------------+--------------------------
 PREPROCESS | QUEUED      | rag-demo/scaling.md
 PREPROCESS | QUEUED      | rag-demo/backups.md
 PREPROCESS | QUEUED      | rag-demo/availability.md


Summarize the queue:

				
					SELECT
    task_type,
    task_status,
    count(*) AS tasks
FROM dist_rag.work_queue
GROUP BY
    task_type,
    task_status
ORDER BY
    task_type,
    task_status;


Output:

				
					 .task_type  | task_status | tasks
------------+-------------+-------
 PREPROCESS | QUEUED      |     3


The documents themselves are also still queued:

				
					SELECT
    document_name,
    status
FROM dist_rag.documents
WHERE source_id = :'source_id'::uuid
ORDER BY document_name;


Output:

				
					.     document_name       | status
--------------------------+--------
 rag-demo/availability.md | QUEUED
 rag-demo/backups.md      | QUEUED
 rag-demo/scaling.md      | QUEUED
				
			
This Is Where Distributed Preprocessing Begins

build_index() creates one PREPROCESS task for each eligible document. Independent workers can claim different tasks, allowing document preprocessing to scale horizontally.

Step 9: Start the Worker and Process the Documents

Restart the worker:

				
					python __main__.py


The worker now claims the PREPROCESS tasks.

For each document it performs the expensive work outside the database:

Download
|
v
Parse
|
v
Chunk
|
v
Generate Embeddings
|
v
Persist in YugabyteDB

Because our demo documents are tiny, processing finishes quickly.

Check the work queue again:

				
					SELECT
    task_type,
    task_status,
    count(*) AS tasks
FROM dist_rag.work_queue
GROUP BY
    task_type,
    task_status;


Output:

				
					(0 rows)


All live work has been consumed.

Step 10: Verify the Document Status

Run:

				
					SELECT
    document_name,
    status
FROM dist_rag.documents
WHERE source_id = :'source_id'::uuid
ORDER BY document_name;


Our run returned:

				
					.     document_name       |  status
--------------------------+-----------
 rag-demo/availability.md | COMPLETED
 rag-demo/backups.md      | COMPLETED
 rag-demo/scaling.md      | COMPLETED


Step 11: Monitor the Pipeline

The work queue tells us what work is currently waiting to be executed.

The pipeline views tell us what happened while processing each document.

Run:

				
					SELECT
    index_name,
    document_name,
    pipeline_status,
    chunks_processed,
    embeddings_persisted,
    current_step,
    last_error_message
FROM dist_rag.vector_index_pipeline_details
WHERE index_name = 'rag_demo_kb'
ORDER BY document_name;


Our run produced:

				
					.index_name  |      document_name       | pipeline_status | chunks_processed | embeddings_persisted
-------------+--------------------------+-----------------+------------------+----------------------
 rag_demo_kb | rag-demo/availability.md | COMPLETED       |                4 |                    4
 rag_demo_kb | rag-demo/backups.md      | COMPLETED       |                4 |                    4
 rag_demo_kb | rag-demo/scaling.md      | COMPLETED       |                4 |                    4


All three last_error_message values were empty.

Now look at the aggregated statistics:

				
					SELECT
    index_name,
    document_name,
    calls,
    total_chunks_processed,
    total_embeddings_persisted,
    completion_rate_percent
FROM dist_rag.pipeline_stats
WHERE index_name = 'rag_demo_kb'
ORDER BY document_name;


Output:

				
					.index_name  |      document_name       | calls | total_chunks_processed | total_embeddings_persisted | completion_rate_percent
-------------+--------------------------+-------+------------------------+----------------------------+-------------------------
 rag_demo_kb | rag-demo/availability.md |     1 |                      4 |                          4 |                  100.00
 rag_demo_kb | rag-demo/backups.md      |     1 |                      4 |                          4 |                  100.00
 rag_demo_kb | rag-demo/scaling.md      |     1 |                      4 |                          4 |                  100.00


That is exactly what we want from a clean run:

				
					3 Documents

1 Pipeline Call Each

4 Chunks Each

4 Embeddings Each

100% Completion


Step 12: Understand the Three Layers of State

At this point, it is useful to distinguish the three major objects we have been querying.

Object What It Tells You
dist_rag.work_queue What work is currently waiting for or being handled by workers.
dist_rag.documents The processing state of each document discovered from a source.
dist_rag.pipeline_details The processing record for document preprocessing, including chunks, embeddings, timing, and errors.

Put another way:

				
					dist_rag.work_queue
        |
        +--> What work needs to run?


dist_rag.documents
        |
        +--> What state is this document in?


dist_rag.pipeline_details
        |
        +--> What happened while processing it?


That separation is one of the more useful operational aspects of the extension.

Step 13: Verify the Stored Chunks

Count the rows in the generated knowledge-base table:

				
					SELECT count(*) AS chunks_stored
FROM public.rag_demo_kb;


Output:

				
					.chunks_stored
---------------
            12


Now count by source document:

				
					SELECT
    d.document_name,
    count(*) AS chunks
FROM public.rag_demo_kb kb
JOIN dist_rag.documents d
  ON d.document_id = kb.document_id
GROUP BY d.document_name
ORDER BY d.document_name;


Output:

				
					.     document_name       | chunks
--------------------------+--------
 rag-demo/availability.md |      4
 rag-demo/backups.md      |      4
 rag-demo/scaling.md      |      4


So the final result is:

				
					availability.md
      |
      +--> 4 chunks

backups.md
      |
      +--> 4 chunks

scaling.md
      |
      +--> 4 chunks

Total
      |
      +--> 12 chunks


Step 14: Inspect the Chunks and Metadata

Run:

				
					SELECT
    d.document_name,
    LEFT(kb.chunk_text, 100) AS chunk_preview,
    kb.metadata_filters
FROM public.rag_demo_kb kb
JOIN dist_rag.documents d
  ON d.document_id = kb.document_id
ORDER BY
    d.document_name,
    kb.chunk_text;


Example output:

				
					rag-demo/availability.md | # Availability
rag-demo/availability.md | Database maintenance should be performed gradually...
rag-demo/availability.md | Production changes must be validated...
rag-demo/availability.md | The Acme Payments production service is deployed...

rag-demo/backups.md      | # Backups
rag-demo/backups.md      | A backup should not be considered useful...
rag-demo/backups.md      | Backup jobs are monitored...
rag-demo/backups.md      | The Acme Payments platform creates scheduled backups...

rag-demo/scaling.md      | # Scaling
rag-demo/scaling.md      | Scaling decisions should consider CPU utilization...
rag-demo/scaling.md      | The Acme Payments operations team monitors...
rag-demo/scaling.md      | When sustained workload growth requires...


Every row also contains:

				
					{
  "demo": "rag_series",
  "content_type": "operations"
}


That metadata originated here:

				
					r_metadata := '{
    "demo": "rag_series",
    "content_type": "operations"
}'::jsonb


and followed the documents all the way into the generated vector rows.

This becomes particularly useful later when vector similarity needs to be combined with relational filtering.

Step 15: Verify the Embeddings

We specified:

				
					{
    "model": "text-embedding-3-small",
    "dimensions": 1536
}


Let’s verify what was actually stored:

				
					SELECT
    vector_dims(embeddings) AS dimensions,
    count(*) AS vectors
FROM public.rag_demo_kb
GROUP BY vector_dims(embeddings);


Output:

				
					.dimensions | vectors
------------+---------
       1536 |      12


So our pipeline has now definitively produced:

12 Document Chunks
|
v
12 OpenAI Embeddings
|
v
1536 Dimensions Each
|
v
Stored in YugabyteDB

Verify the Data, Not Just the Status

A COMPLETED pipeline status is useful, but querying the backing table confirms that the document chunks and actual vector embeddings were persisted into YugabyteDB.

Step 16: Test Vector Similarity Search

A real RAG application generates an embedding from the user’s question and searches for nearby document embeddings.

The retrieval query eventually looks something like:

				
					SELECT
    chunk_text,
    embeddings <=> :query_embedding AS distance
FROM public.rag_demo_kb
ORDER BY embeddings <=> :query_embedding
LIMIT 5;


For now, we can perform a database-only smoke test by using one stored embedding as the query vector:

				
					WITH query_vector AS (
    SELECT embeddings
    FROM public.rag_demo_kb
    LIMIT 1
)
SELECT
    d.document_name,
    LEFT(kb.chunk_text, 100) AS chunk_preview,
    kb.embeddings <=> q.embeddings AS distance
FROM public.rag_demo_kb kb
JOIN dist_rag.documents d
  ON d.document_id = kb.document_id
CROSS JOIN query_vector q
ORDER BY distance
LIMIT 5;


Our run returned:

				
					.     document_name       | chunk_preview                                  | distance
--------------------------+------------------------------------------------+--------------------
 rag-demo/scaling.md      | Scaling decisions should consider CPU...       | 0
 rag-demo/scaling.md      | # Scaling                                      | 0.5053490405552588
 rag-demo/scaling.md      | When sustained workload growth requires...     | 0.5193721143627461
 rag-demo/availability.md | Database maintenance should be performed...    | 0.5213339511767097
 rag-demo/scaling.md      | The Acme Payments operations team monitors...  | 0.5956710929450477


The first distance is:

because the query vector is being compared with itself.

The remaining rows demonstrate vector-distance ordering.

This Is a Vector Search Smoke Test

Using an existing stored embedding verifies that vector similarity search is working. A real RAG application instead generates an embedding from the user’s question using a compatible embedding model and uses that vector for retrieval.

We will do exactly that in Part 3.

Step 17: Scale Out the Workers

Our demo only contains 3 documents so one worker is more than enough.

But imagine 3 documens becoming 3,000,000 documents!

The architecture does not fundamentally change.

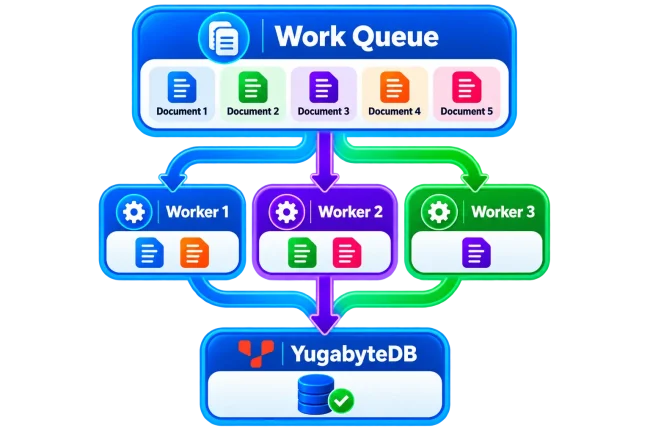
Multiple workers can claim different tasks from dist_rag.work_queue.

The resulting architecture looks like:

YB-Work-Queue

Workers can therefore scale independently from YugabyteDB.

TEXT and PDF workers can also be scaled separately.

Why This Matters

YugabyteDB manages the durable RAG state and work coordination, while the compute-intensive preprocessing tier can scale independently. More document-ingestion throughput does not require moving the vector data to a separate database.

What Did We Actually Build?

With a handful of SQL calls we created this:

Full-RAG-Pipeline

Note that there is…

  • ● No custom application work queue.
  • ● No custom document-state table.
  • ● No custom pipeline-monitoring schema.
  • ● And no separate vector database.

The extension and workers coordinate the preprocessing pipeline while the resulting chunks, metadata, and vectors land directly in YugabyteDB.

The Four Functions to Remember

The basic workflow boils down to four functions.

Function Purpose
dist_rag.create_source() Register a document collection and queue source discovery.
dist_rag.init_vector_index() Create the pgvector-backed knowledge-base table and HNSW index.
dist_rag.add_source_to_index() Attach additional document sources to an existing vector index.
dist_rag.build_index() Queue document preprocessing, chunking, and embedding generation.

Final Takeaway

pgvector gives YugabyteDB the ability to store embeddings and perform vector similarity search.

pg_dist_rag tackles a different problem:

  • How do those embeddings get there in the first place?

Instead of building a separate ingestion framework to discover documents, coordinate work, track document state, invoke embedding services, persist vectors, and monitor processing, pg_dist_rag makes YugabyteDB the control plane for the preprocessing pipeline.

dist_rag.work_queue is a particularly important piece of that architecture. It provides the live database-backed handoff between YSQL and independently scalable external workers.

The worker performs the computationally expensive operations.

YugabyteDB coordinates and tracks the work, and the resulting chunks, embeddings, tenant identifiers, and metadata land directly in a pgvector-backed YSQL table.

The next question is where this architecture becomes particularly interesting:

  • What happens when the same RAG platform needs to support many different customers or tenants?

Which is exactly where we are going next.

Up Next

We will take what we built here and make it much more interesting:

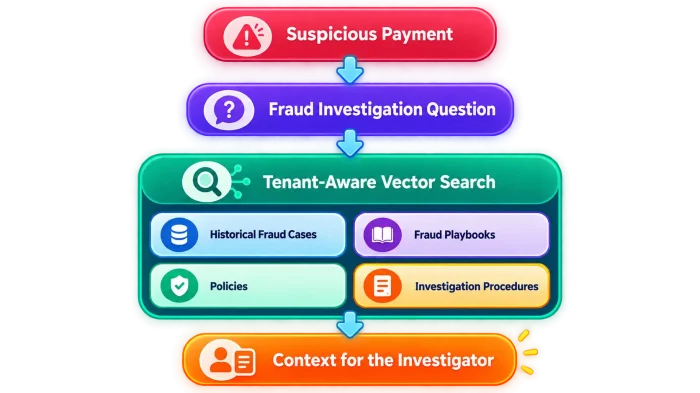
RAG-Fraud

And critically:

  • Bank A -> Bank A knowledge only
  • Bank B -> Bank B knowledge only
  • Bank C -> Bank C knowledge only

That will let us combine three things YugabyteDB is particularly well positioned to bring together:

  • distributed SQL + vector search + multi-tenant application data.

References

Have Fun!

While shopping at the local Walmart near my son’s new house to help fill his fridge with food, we saw THIS!

My heart almost exploded with joy. 😂 I thought Sixlets had been discontinued a few years ago, but there they were… in all their glorious, chocolatey goodness! I absolutely LOVE this candy. And see that empty hook there in the middle?

Yeah… that was occupied by the six bags of Sixlets that are now sitting in our shopping cart. 😂

Some people get excited about finding rare collectibles. Apparently, I get excited about finding Sixlets at Walmart. 😄🍫🛒