While attending the Postgres Summit in New York City last week, someone stopped by the YugabyteDB display and asked me an interesting question:
- How do I know that a Raft replica really received the data… and that the copy is intact?
I gave him the high-level answer about Raft consensus, replication factor, and quorum, but it was pretty obvious he was looking for something more concrete:
- How does YugabyteDB actually verify that the replicated data wasn’t corrupted, and is there a way to prove that the replicas really contain the same data?
My first thought was: is there some sort of hash we can run against the files on each replica?
And what about under-replicated tablet warnings? Does that mean replication failed or that the replicas don’t match?
I decided to dig into the YugabyteDB documentation and open source code to find a more complete answer.
As it turns out, the answer is a lot more interesting than a single checksum.
First: What Does Raft Already Guarantee?
Every YugabyteDB tablet is represented by a group of tablet peers. With a replication factor of 3, there are normally three copies of the tablet hosted on different YB-TServers.
Those peers form a Raft group.
One peer is elected leader, and writes flow through that leader. The leader replicates the corresponding Raft log entry to its followers.
Receiving the write at the tablet leader is not enough. The write must first be successfully replicated through Raft.
For user-table writes, the tablet leader uses Raft to replicate the write to a quorum of tablet peers. Once the Raft subsystem reports successful replication, the leader applies the write to its local DocDB and can acknowledge success to the client. Followers learn the updated commit state and apply the entry to their own DocDB state afterward.
This is an important distinction:
- Raft ensures that the write is durably replicated to a quorum before success is acknowledged to the client.
It does not necessarily mean every follower is caught up at that exact instant.
A slow follower can temporarily lag and later catch up while the cluster continues serving writes as long as a quorum remains healthy.
There Are Multiple Integrity Layers
Rather than one universal checksum, YugabyteDB has several mechanisms that protect different parts of the replication and storage path.
| Layer | What It Helps Verify |
| Raft Consensus | Replicates the write to a quorum of tablet peers; once Raft reports successful replication, the data is durable and the leader can acknowledge success to the client. |
| Raft WAL Checksums | Detects corruption while reading/recovering Raft log data. |
| Remote Bootstrap CRC32C | Verifies chunks transferred while constructing a replacement tablet replica. |
| Local Tablet Integrity Check | Opens a tablet’s regular and intents RocksDB databases with integrity checking enabled. |
| Logical Replica Hash | Lets you compare the logical tablet contents returned by each replica at the same read time. |
Rebuilding a Tablet Replica Is Checksummed Too
Suppose a tablet peer hosted by a YB-TServer fails and YugabyteDB needs to create a replacement.
YugabyteDB can use remote bootstrap to copy the necessary tablet data from a healthy peer to the replacement peer. For under-replicated tablets, YugabyteDB can automatically create replacement tablet replicas from the remaining healthy peers when sufficient capacity is available.
The source code adds an important integrity check to that process.
In remote_bootstrap_file_downloader.cc, every downloaded chunk is passed through VerifyData(). The receiver calculates a CRC32C over the received data and compares it with the CRC supplied with the chunk.
If they differ, the operation returns a Corruption error rather than silently accepting the data.
So a replacement tablet replica is not simply accepting a blind network file copy… each transferred chunk is integrity-checked before it is accepted.
What About Checking the Data Already on Disk?
There is also a YB-TServer flag named:
--verify_tablet_data_interval_sec
The current flag definition says it controls a tablet data integrity verification background task and defaults to 0, meaning the task is disabled.
When enabled, the background task periodically walks the running tablet peers and calls:
Tablet::VerifyDataIntegrity()
Tablet::VerifyDataIntegrity() checks both the tablet’s regular RocksDB database and its intents RocksDB database. As part of that process, each database is opened read-only with:
paranoid_checks = true
and reports detected RocksDB corruption.
There is an important nuance here, though.
The current source also contains a TODO noting that additional block-content/checksum verification could be added. So I would describe this as a local RocksDB integrity check, not as an exhaustive background scan that reads and hashes every byte of every SST file.
verify_tablet_data_interval_sec checks the health of the
local tablet storage.
So How Can I Compare the Actual Replicas?
This gets closest to the original question from the booth:
- Can I verify that the replicas actually contain the same data?
In newer YugabyteDB builds, a low-level yb-ts-cli command can dump or hash tablet data.
The form used in current engineering diagnostics is:
					yb-ts-cli --server_address=<peer> \
  dump_tablet_data <tablet_id> HASH_ONLY <read_ht>
Run the comparison against every peer for the tablet using the same pinned read hybrid time. Current YugabyteDB engineering guidance also recommends quiescing the workload for this type of forensic comparison so that ordinary replication lag isn’t mistaken for divergence.
Conceptually:
| Tablet Peer | Same Read Time | Logical Hash |
| Replica A | HT = X | HASH ABC123 |
| Replica B | HT = X | HASH ABC123 |
| Replica C | HT = X | HASH ABC123 |
If all three hashes agree at the same read point, the replicas agree on the logical tablet contents represented by that comparison.
YugabyteDB’s 2026.1 release notes specifically mention fixes for using yb-ts-cli dump_tablet_data on YSQL tablets, so this is something I would treat as version-dependent low-level diagnostic tooling, not assume is identical on every older release.
Why Not Just Hash the SST Files?
This was one of the first things that occurred to me.
Why not calculate something like:
					SHA256(replica-A/*.sst)
SHA256(replica-B/*.sst)
SHA256(replica-C/*.sst)
and compare the results?
Because the physical files are not the logical database.
DocDB uses a customized RocksDB storage engine. Each replica can flush memtables and compact its LSM tree independently. Two perfectly healthy replicas can therefore have different SST file boundaries, different file names, and different physical layouts while representing the same logical rows.
The thing you care about is:
- Does each replica return the same logical tablet state at the same read point?
Not:
- Are the bytes and file boundaries on disk identical?
What About yb-ysck?
This was an interesting source-code rabbit hole.
YugabyteDB contains a yb-ysck implementation with replica checksum logic. It gathers checksum results from replicas, reports a mismatch if one differs from the first result, and returns a corruption status when checksum mismatches are detected.
That sounds perfect for this Tip.
Except there is an important detail in the current source:
					if (table->table_type() == PGSQL_TABLE_TYPE)
  continue;
In other words, the current yb-ysck checksum path skips PostgreSQL/YSQL tables.
yb-ysck Is the YSQL Answer
yb-ysck,
but the current implementation explicitly skips PGSQL_TABLE_TYPE.
yb-ysck will compare the table.
Does an Under-Replicated Tablet Mean the Data Is Bad?
No.
An under-replicated tablet means the number of available/live copies of that tablet is below the desired replication count.
For example, with RF3:
					Expected replicas: 3
Available replicas: 2
That tablet is under-replicated.
The reason could be a failed YB-TServer, an unreachable node, or a replacement replica that has not finished being created yet. YugabyteDB Anywhere even uses under-replication as a safety pre-check before rolling operations.
The YB-Master UI exposes this health state at:
http://<yb-master>:7000/tablet-replication
YugabyteDB’s own upgrade procedure specifically recommends verifying that there are no leaderless or under-replicated tablets there before starting an upgrade.
One More Important Caveat
Even identical replica hashes only answer:
- Do these replicas agree?
They do not necessarily answer:
- Is this the data my application intended to store?
If all replicas contain the same incorrect value because of an application error, or because the same incorrect state was replicated consistently, a replica comparison can still match.
The same idea applies to index consistency.
A table’s replicas could agree perfectly with one another while an index is still inconsistent with its base table. Replica integrity tells you whether copies of the same tablet agree; index consistency asks whether the index accurately reflects the underlying table.
That requires a different check.
yb_index_check(),
which compares an index with its underlying table and can detect
missing, extra, or mismatched index entries.
So How Would I Answer the Question at the Booth Now?
After digging through the code, my short answer would be:
Final Takeaway
There isn’t one magic “Is my replica good?” checksum in YugabyteDB.
Different mechanisms answer different questions:
| Question | What Answers It? |
| Did my write reach enough replicas to commit safely? | Raft quorum |
| Was a replacement replica copied without transfer corruption? | Remote bootstrap CRC32C verification |
| Does the local tablet storage show signs of corruption? | Tablet/RocksDB integrity verification |
| Do the replicas contain the same logical tablet data? | Compare logical hashes at the same read hybrid time |
| Do I currently have all the replicas required by RF? | Under-replicated tablet monitoring |
Have Fun!
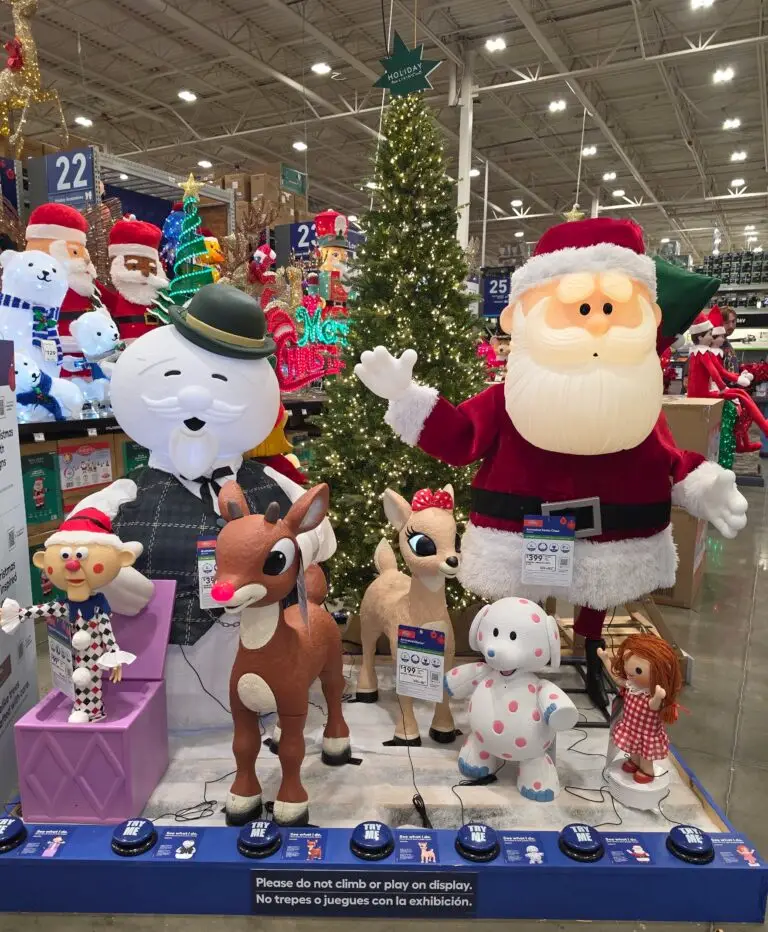
Lowe’s had almost all our favorite characters from Rudolph the Red-Nosed Reindeer on display!
I’d love to bring them home for the front lawn at our new house this year. 🎄🦌
But they’re missing one fan favorite. Any guesses?
Yukon Cornelius! Where’s our favorite prospector? ⛏️😂