Declarative Partitioning in YugabyteDB: Great for Data Purging… But Know the Trade-Offs

YugabyteDB supports PostgreSQL-style declarative table partitioning, including RANGE, LIST, and HASH partitioning.

That can be especially useful for large tables where data has a natural lifecycle, for example, retaining 12 months of history and regularly removing the oldest month.

However, there is an important YugabyteDB-specific distinction:

  • ● YugabyteDB already distributes and shards tables automatically at the DocDB storage layer.
  • ● YSQL declarative partitioning adds a second layer of partitioning on top of that distributed storage.
💡 When Declarative Partitioning Makes Sense
Declarative partitioning is a very good fit in YugabyteDB when the goal is data lifecycle management, such as quickly purging old data, or when partitions need different geographic placement.
I would not introduce SQL partitions simply to make a large table scalable. DocDB already handles that through distributed tablets and automatic tablet splitting.
The main trade-offs are queries that cannot prune partitions, the lack of global unique indexes across partitions, and the additional tablet/index overhead created by every child partition.

Two Different Kinds of Partitioning

It helps to separate two concepts that are sometimes both called “partitioning.”

LayerPurposeManaged By
DocDB shardingDistribute rows and indexes across nodes for scale and availabilityYugabyteDB automatically
YSQL declarative partitioningSeparate data by lifecycle, time, tenant, geography, or another business boundaryDatabase schema / application

Each YSQL partition is a separate table underneath the partitioned parent, and each of those tables is itself distributed across YugabyteDB tablets.

That means the two mechanisms work together:

YSQL Partitioned Table
January Partition
↓
DocDB Tablet(s)
February Partition
↓
DocDB Tablet(s)
March Partition
↓
DocDB Tablet(s)

A Simple Time-Based Example

Suppose we have a large table containing change history:

				
					CREATE TABLE order_changes (
    change_date  DATE NOT NULL,
    id           BIGINT GENERATED BY DEFAULT AS IDENTITY,
    type         TEXT,
    description  TEXT,
    PRIMARY KEY (change_date, id)
)
PARTITION BY RANGE (change_date);


We can create monthly partitions:

				
					CREATE TABLE order_changes_2026_01
PARTITION OF order_changes
FOR VALUES FROM ('2026-01-01') TO ('2026-02-01');

CREATE TABLE order_changes_2026_02
PARTITION OF order_changes
FOR VALUES FROM ('2026-02-01') TO ('2026-03-01');

CREATE TABLE order_changes_2026_03
PARTITION OF order_changes
FOR VALUES FROM ('2026-03-01') TO ('2026-04-01');


The lower boundary is inclusive and the upper boundary is exclusive.

Rows inserted into the parent automatically go to the appropriate child partition.

Why This Is Great for Purging

Without partitioning, removing millions or billions of old rows may require a large DELETE:

				
					DELETE FROM order_changes
WHERE change_date < DATE '2025-01-01';


That is real DML. It creates distributed writes, transaction work, tombstones, and eventual compaction work.

With time-based partitioning, old data can instead be removed at the partition level:

				
					ALTER TABLE order_changes
DETACH PARTITION order_changes_2025_01;

DROP TABLE order_changes_2025_01;


That is fundamentally different from deleting every row individually.

🧹 This Is the Sweet Spot
If the reason for partitioning is, “We need to purge old data efficiently,” then declarative partitioning is a very reasonable YugabyteDB design.
Instead of issuing potentially massive distributed DELETE operations, you can detach and drop an entire old partition.

Concern #1: Indexes Are Local to Each SQL Partition

This is probably the most important query-performance consideration.

Suppose we create an index on the partitioned parent:

				
					CREATE INDEX order_changes_type_idx
ON order_changes (type);


YSQL creates corresponding indexes for the individual child partitions.

There is not one global index spanning all declarative partitions.

That distinction matters when executing queries.

Query That Includes the Partition Key

Consider:

				
					SELECT *
FROM order_changes
WHERE change_date >= DATE '2026-03-01'
  AND change_date <  DATE '2026-04-01'
  AND type = 'ADDRESS';


The planner knows that only the March partition can contain those rows.

Partition pruning can eliminate the other partitions before accessing their tables or indexes.

That is exactly what we want.

Query Without the Partition Key

Now consider:

				
					SELECT *
FROM order_changes
WHERE type = 'ADDRESS';


There is no change_date predicate.

The planner cannot eliminate partitions based on the partition key, so it may need to search the type index belonging to every applicable partition.

With three partitions, that might be trivial. With 12 or 24 partitions, it may still be perfectly reasonable.

With hundreds of partitions, the query can become much more expensive because the SQL layer must coordinate work across many child relations and potentially many distributed tablets.

⚠️ Partition Count Matters
Avoid creating extremely fine-grained partitions unless the retention requirements actually require them.
For example, if monthly partitions satisfy the purge requirement, creating daily partitions usually adds complexity and overhead without providing additional scaling benefits.

Verify Partition Pruning

Don’t assume that a query is pruning partitions.

Check it:

				
					EXPLAIN (ANALYZE, DIST, COSTS OFF)
SELECT *
FROM order_changes
WHERE change_date >= DATE '2026-03-01'
  AND change_date <  DATE '2026-04-01'
  AND type = 'ADDRESS';


Then compare it with:

				
					EXPLAIN (ANALYZE, DIST, COSTS OFF)
SELECT *
FROM order_changes
WHERE type = 'ADDRESS';


For the second query, look for an Append or Parallel Append accessing multiple child partitions.

Also pay attention to YugabyteDB-specific metrics such as:

  • ● Storage Read Requests
  • ● Storage Rows Scanned
  • ● Number of child scans
  • ● Actual execution time

Those numbers tell you far more than simply looking at whether the plan says Index Scan.

Concern #2: No Global Unique Constraint Across Partitions

PostgreSQL declarative partitioning requires a PRIMARY KEY or UNIQUE constraint on the partitioned parent to contain all partition key columns.

For our example:

				
					PRIMARY KEY (change_date, id)


is valid because change_date is the partition key.

But this:

				
					UNIQUE (id)


cannot provide a global uniqueness constraint across all partitions.

The database would need a single global index spanning all child partitions to enforce that, and PostgreSQL-style declarative partitioning does not provide one.

⚠️ Sequence Does Not Equal Global Constraint
A single sequence or identity generator can make duplicate IDs operationally very unlikely. or impossible if it is the only generator, but that is different from having a database-enforced UNIQUE(id) constraint spanning every partition.

If strict global uniqueness on a non-partition column is required, you’ll need to model that separately.

💡 Need Global Uniqueness Across Partitions?
Although YSQL does not provide a native global unique index across declarative partitions, there are schema-level patterns you can use when global uniqueness is required.
Here are two approaches you can consider:
👉 Enforce Uniqueness Across Partitions – Option 1 — use a check constraint that calls a function to look for an existing value across the partitioned table.
Caveat: this approach performs an additional lookup as part of the constraint check and may not scale well for high-volume INSERTs or bulk loads.
👉 Enforce Uniqueness Across Partitions – Option 2 — maintain the globally unique values in a separate, non-partitioned table backed by a primary key, with a trigger keeping that table synchronized.
Caveat: this adds an additional table write and trigger execution to the INSERT path, so it can also become a scalability consideration for write-heavy workloads.
These are workaround patterns, not native global indexes. Test their concurrency, write throughput, and operational behavior carefully with your actual workload before choosing either approach.
Concern #3: Every Partition Adds Tablets

A declarative partition is not simply a logical boundary.

Each child partition is a separate distributed YugabyteDB table. Each secondary index on that partition is another distributed YugabyteDB relation.

So a rough way to think about the footprint is:

Total Logical Tablets
≈
Tablets for All Child Tables
+
Tablets for All Child Secondary Indexes

And with replication:

Tablet Replicas
≈
Logical Tablets
×
Replication Factor

For example, imagine:

Assumptions
12 Monthly Partitions
1 Tablet per Child Table
2 Secondary Indexes per Partition
Replication Factor = 3

Before any automatic tablet splitting:

Calculation
12 × (1 Table + 2 Indexes)
=
36 Logical Tablets
36 × RF3
=
108 Tablet Replicas

That is only an illustrative example… the actual starting tablet count depends on the YugabyteDB configuration, schema, and version, and tablets may automatically split as the data grows.

The important point is that partition count and index count multiply each other.

Don’t Over-Presplit the Partitions

YugabyteDB supports automatic tablet splitting, so for most workloads it makes sense to:

  • ● Start with a conservative number of tablets.
  • ● Let automatic tablet splitting grow large partitions.
  • ● Use SPLIT INTO when initial parallelism is actually required by a high-ingest workload.
  • ● Monitor real tablet distribution instead of calculating a large presplit count up front.
💡 Remember
Declarative partitioning already increases the number of physical relations. There is usually no reason to multiply that again by aggressively presplitting every child partition and every child index.

Check the Actual Tablet Count

On YugabyteDB versions that provide the yb_tablet_metadata view, you can see the tablets backing the leaf partitions.

For example:

				
					SELECT
    pt.relid::regclass AS partition_name,
    COUNT(ytm.tablet_id) AS tablets
FROM pg_partition_tree('order_changes'::regclass) pt
LEFT JOIN yb_tablet_metadata ytm
       ON ytm.oid = pt.relid
WHERE pt.isleaf
GROUP BY pt.relid
ORDER BY pt.relid::regclass::text;


You can also examine the secondary indexes belonging to each partition:

				
					SELECT
    child.relname AS partition_name,
    idx.relname   AS index_name,
    COUNT(ytm.tablet_id) AS tablets
FROM pg_partition_tree('order_changes'::regclass) pt
JOIN pg_class child
  ON child.oid = pt.relid
JOIN pg_index i
  ON i.indrelid = child.oid
JOIN pg_class idx
  ON idx.oid = i.indexrelid
LEFT JOIN yb_tablet_metadata ytm
  ON ytm.oid = idx.oid
WHERE pt.isleaf
  AND NOT i.indisprimary
GROUP BY child.relname, idx.relname
ORDER BY child.relname, idx.relname;


This is much better than guessing how many tablets the partition hierarchy has created.

Will Inserts Be Slower?

There is some additional SQL-layer routing involved because YugabyteDB first determines the appropriate declarative partition.

But once the partition has been identified, the row is written to the tablets backing that child table and its indexes just like other YugabyteDB writes. With a reasonable number of partitions, I would not assume that partitioning automatically means a significant INSERT performance penalty.

Benchmark the actual workload.

The bigger performance concern tends to be reads that cannot take advantage of partition pruning, not the act of routing an INSERT into one of a modest number of partitions.

How Many Partitions Should You Create?

There isn’t one magic number.

The better question is:

  • What is the largest partition interval that still satisfies the lifecycle requirement?

If the requirement is:

  • Keep one year of data and purge once per month.

Then monthly partitions are an obvious place to start:

12 Active Monthly Partitions
+
A Few Future Partitions

There is usually no benefit to creating 365 daily partitions if the application only purges once per month.

Similarly, if quarterly retention boundaries work, four quarterly partitions may be even simpler.

Use the minimum number of declarative partitions needed to accomplish the operational goal, and let YugabyteDB tablets handle the scale within each partition.

Automating Time-Based Partitions

Manually creating the next month’s partition is easy to forget.

For environments with ongoing time-based partition maintenance, YugabyteDB also supports the pg_partman extension.

For example, pg_partman can pre-create future monthly partitions and automate retention maintenance.

There are YugabyteDB-specific considerations with pg_partman, so review its documented limitations before relying on it… particularly around default partitions, maintenance scheduling, and replicated environments.

Other Partitioning Details to Remember

Item Consideration
Primary key Must include the declarative partition key.
Unique constraints Must include the partition key; there is no global unique index spanning all partitions.
Indexes Indexes on the partitioned parent correspond to indexes on the individual child partitions.
Tablespaces Partitions can be combined with YugabyteDB tablespaces for geographic placement.
Existing tables A regular table cannot simply be converted into a partitioned table, although compatible tables can be attached as partitions.
Default partition Useful in some designs, but adding a new partition requires ensuring the default partition contains no rows belonging in the new range.

Practical Recommendation

For a large YugabyteDB table where the primary motivation is purging historical data, I would absolutely consider declarative range partitioning by time.

But I would design it with a few rules:

    1. Partition for lifecycle… not for scale. Let DocDB tablets provide horizontal scale.
    2. Choose the coarsest useful interval. Monthly or quarterly partitions are often preferable to daily partitions when retention allows it.
    3. Make partition pruning part of the query design. High-frequency queries should include the partition key whenever practical.
    4. Identify queries that cannot include the partition key. Benchmark those carefully because they may need to search local indexes across every partition.
    5. Decide up front whether global uniqueness is required. A partitioned design may require changing how that constraint is modeled.
    6. Keep tablet counts conservative. Let automatic tablet splitting do its job rather than heavily presplitting every partition.
    7. Measure instead of guessing. Use EXPLAIN (ANALYZE, DIST) and yb_tablet_metadata to see the actual distributed work being performed.
✅ Bottom Line
PostgreSQL-style declarative partitioning works well in YugabyteDB when there is a real reason to create logical data boundaries, especially fast retention/purging and geographic placement.
Just remember that every SQL partition is already a distributed YugabyteDB table underneath. Keep the number of partitions reasonable, design queries so partition pruning can occur, and let DocDB handle the actual horizontal scaling.

Have Fun!

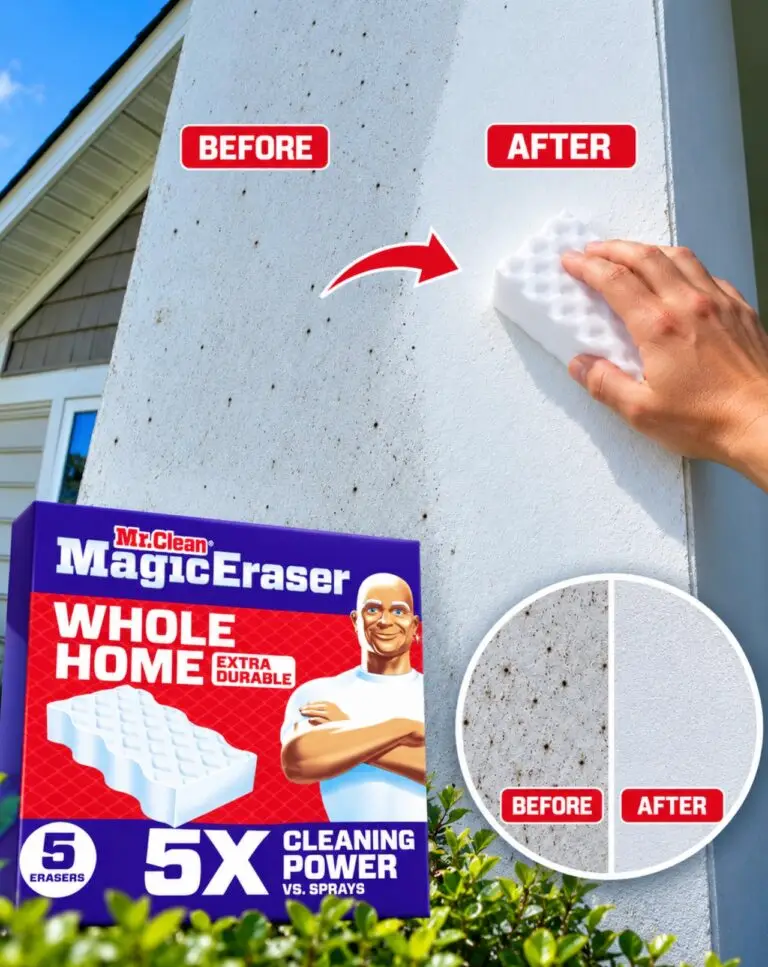
We could not figure out what these tiny black dots all over the house were, so naturally we asked AI. 😂

Turns out our nice black wood mulch was growing artillery fungus… which literally shoots sticky little black spores at your house.

Yep. Our mulch was apparently armed. 🎯🍄

The good news: Magic Erasers actually work!

The bad news: there were approximately 47 billion spots, and cleaning them off took FOREVER. 😩

So we have now replaced the offending mulch with rubber mulch.

Consider this a public service announcement:

if mysterious black dots start appearing on your siding, check your mulch before your house becomes a fungal shooting range. 😂

⚠️ You have been warned!